Can Terraform provision on-premises infrastructure? Yes - vSphere, Proxmox, libvirt, MAAS, Docker and plain SSH, with a real apply and the honest limits (Terraform 1.14)

TL;DR
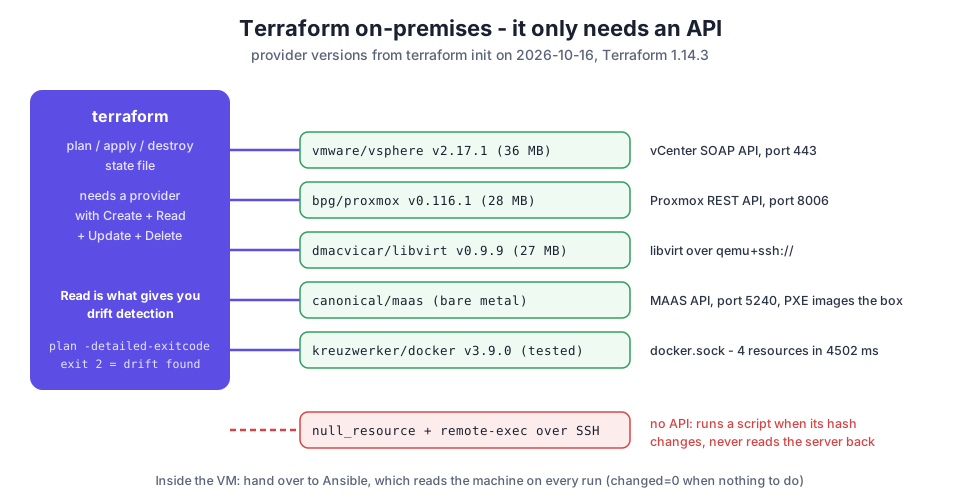
- Yes. Terraform does not care where the API lives. On-premises it talks to vCenter (
vmware/vsphere), Proxmox VE (bpg/proxmox), libvirt/KVM (dmacvicar/libvirt), Canonical MAAS for bare metal (canonical/maas) or a Docker engine (kreuzwerker/docker), and the plan/apply/destroy loop is identical to AWS. - The requirement is an API. A rack of servers with only SSH has no API, so Terraform can run scripts on them (
null_resource+remote-exec) but cannot read their state back; drift detection, the thing Terraform is for, does not exist there. Put a management layer in front (MAAS, Proxmox, vSphere) or hand the servers to Ansible. - Measured on Terraform 1.14.3: the Docker provider created a network, an image and 2 containers in 4502 ms, and after I removed one container by hand
terraform planreported exactly1 to add(exit code 2). The vSphere, Proxmox and libvirt providers are 36 MB, 28 MB and 27 MB and all passterraform validatewithout any credentials. - Without a reachable vCenter the plan fails at the provider, not the resource:
error setting up new vSphere SOAP client ... lookup vcenter.example.internal: no such host. - Everything below ran on 2026-10-16 on an Ubuntu 24.04 runner with Docker 28.0.4; the vSphere, Proxmox and libvirt sections are init and validate only, because I do not have those APIs on a laptop.
- Not your exact case? The closest post on this site is Terraform Guide.
The 2023 version of this post was a tour of the options. The question behind it is usually "will Terraform give me the same workflow on our own hardware as on AWS", and the answer depends on one thing: whether there is an API in front of the hardware. So this rewrite is organised around that, with a real apply where I could run one.
Table of Content
- The one rule - Terraform needs an API, not a server
- A real apply - the Docker provider against your own engine
- Drift - what happens when someone deletes a VM by hand
- vSphere, Proxmox and libvirt - init, validate and the unreachable-vCenter error
- Bare metal - MAAS
- Plain servers over SSH - null resource and remote-exec
- Where Ansible takes over
- What broke when I ran this
- Conclusion
1. The one rule - Terraform needs an API, not a server
| On-prem platform | Provider | What Terraform manages | Can it detect drift? |
|---|---|---|---|
| VMware vSphere / vCenter | vmware/vsphere v2.17.1 | VMs, datastores, networks, folders, tags | yes |
| Proxmox VE | bpg/proxmox v0.116.1 | VMs, LXC containers, storage, users | yes |
| KVM / libvirt | dmacvicar/libvirt v0.9.9 | domains, volumes, networks, cloud-init disks | yes |
| Bare metal | canonical/maas | machines, deployments, VLANs, subnets | yes |
| Docker engine | kreuzwerker/docker v3.9.0 | images, containers, networks, volumes | yes |
| A server with only SSH | null_resource + remote-exec | runs a script once | no |
Versions are the ones terraform init picked on 2026-10-16. The last row is the important one: everything above it has a Read operation, so terraform plan can compare reality with the state file. Over bare SSH there is nothing to read.
2. A real apply - the Docker provider against your own engine
The Docker provider is the on-prem provider everyone already has, and it behaves exactly like the hypervisor providers: a daemon on your machine, an API socket, and resources that Terraform can create and read back. Two nginx containers on a private network:
 1terraform {
 2  required_providers {
 3    docker = { source = "kreuzwerker/docker", version = "~> 3.0" }
 4  }
 5}
 6provider "docker" {}
 7
 8resource "docker_image" "nginx" {
 9  name         = "nginx:1.27-alpine"
10  keep_locally = true
11}
12
13resource "docker_network" "app" {
14  name = "onprem-app"
15}
16
17resource "docker_container" "web" {
18  count = 2
19  name  = "onprem-web-${count.index + 1}"
20  image = docker_image.nginx.image_id
21  networks_advanced { name = docker_network.app.name }
22  ports {
23    internal = 80
24    external = 8080 + count.index
25  }
26}
27
28output "urls" { value = [for c in docker_container.web : "http://localhost:${c.ports[0].external}"] }
 1$ terraform version
 2Terraform v1.14.3
 3
 4$ terraform init
 5- Installing kreuzwerker/docker v3.9.0...
 6Terraform has been successfully initialized!
 7
 8$ terraform apply -auto-approve
 9docker_image.nginx: Creating...
10docker_network.app: Creating...
11docker_network.app: Creation complete after 3s [id=6728722ab598...]
12docker_image.nginx: Creation complete after 4s [id=sha256:6769dc3a703c...nginx:1.27-alpine]
13docker_container.web[0]: Creating...
14docker_container.web[1]: Creating...
15docker_container.web[1]: Creation complete after 1s [id=086e94f6d191...]
16docker_container.web[0]: Creation complete after 1s [id=7b5a5e1dc81a...]
17Apply complete! Resources: 4 added, 0 changed, 0 destroyed.
18Outputs:
19urls = [
20  "http://localhost:8080",
21  "http://localhost:8081",
22]
23
24$ docker ps --filter name=onprem --format 'table {{.Names}}\t{{.Ports}}\t{{.Status}}'
25NAMES          PORTS                  STATUS
26onprem-web-1   0.0.0.0:8080->80/tcp   Up Less than a second
27onprem-web-2   0.0.0.0:8081->80/tcp   Up Less than a second
28
29$ curl -s -o /dev/null -w '%{http_code}\n' http://localhost:8081/
30200
The whole apply took 4502 ms, most of it the image pull. The provider's defaults are visible in the plan and worth knowing: wait_timeout = 60 (seconds to wait for a healthcheck when wait = true), container_read_refresh_timeout_milliseconds = 15000 (15000 ms for the engine to answer a read), restart = "no", must_run = true. I covered the provider in more depth in Terraform with Docker containers.
3. Drift - what happens when someone deletes a VM by hand
This is the test that separates "Terraform can run on-prem" from "Terraform is useful on-prem". I deleted one container outside Terraform, the way a colleague deletes a VM in the vSphere client:
 1$ docker rm -f onprem-web-2
 2onprem-web-2
 3
 4$ terraform plan -detailed-exitcode
 5docker_container.web[1]: Refreshing state... [id=086e94f6d191...]
 6
 7  # docker_container.web[1] will be created
 8  + resource "docker_container" "web" {
 9      + name = "onprem-web-2"
10      + ports {
11          + external = 8081
12          + internal = 80
13        }
14    }
15
16Plan: 1 to add, 0 to change, 0 to destroy.
17[exit 2]
18
19$ terraform apply -auto-approve
20docker_container.web[1]: Creation complete after 0s [id=72e71ea9d9c4...]
21Apply complete! Resources: 1 added, 0 changed, 0 destroyed.
The refresh noticed the missing container, the plan proposed exactly the missing piece, and -detailed-exitcode returned 2 so a CI job can fail on drift. The vSphere, Proxmox, libvirt and MAAS providers do the same because they all implement Read. terraform destroy then removed all 4 resources and terraform state list was empty.
4. vSphere, Proxmox and libvirt - init, validate and the unreachable-vCenter error
I cannot run a vCenter on a laptop, so for the three hypervisor providers I did what you can do before you have access: declare them, initialise, validate, and see what a plan without the API looks like.
 1terraform {
 2  required_providers {
 3    vsphere = { source = "vmware/vsphere", version = "~> 2.0" }
 4    proxmox = { source = "bpg/proxmox", version = "~> 0.60" }
 5    libvirt = { source = "dmacvicar/libvirt", version = "~> 0.8" }
 6  }
 7}
 8provider "vsphere" {
 9  user                 = "administrator@vsphere.local"
10  password             = var.vsphere_password
11  vsphere_server       = "vcenter.example.internal"
12  allow_unverified_ssl = true
13}
14data "vsphere_datacenter" "dc" { name = "DC1" }
15
16resource "vsphere_virtual_machine" "vm" {
17  name             = "app-01"
18  resource_pool_id = "resgroup-1"
19  datastore_id     = "datastore-1"
20  num_cpus         = 2
21  memory           = 4096
22  guest_id         = "ubuntu64Guest"
23  network_interface { network_id = "network-1" }
24  disk {
25    label = "disk0"
26    size  = 40
27  }
28}
 1$ terraform init
 2- Installing dmacvicar/libvirt v0.9.9...
 3- Installing vmware/vsphere v2.17.1... (signed by a HashiCorp partner)
 4- Installing bpg/proxmox v0.116.1...
 5Terraform has been successfully initialized!
 6
 7$ terraform validate
 8Success! The configuration is valid.
 9
10$ du -sh .terraform/providers/registry.terraform.io/*/* | sort -h
1127M	.terraform/providers/registry.terraform.io/dmacvicar/libvirt
1228M	.terraform/providers/registry.terraform.io/bpg/proxmox
1336M	.terraform/providers/registry.terraform.io/vmware/vsphere
14
15$ terraform plan
16Planning failed. Terraform encountered an error while generating this plan.
17
18Error: error setting up new vSphere SOAP client: Post "https://vcenter.example.internal/sdk":
19dial tcp: lookup vcenter.example.internal on 127.0.0.53:53: no such host
20
21  with provider["registry.terraform.io/vmware/vsphere"],
22  on main.tf line 8, in provider "vsphere":
23   8: provider "vsphere" {
Three things to take from that: validate passes with no API at all, so syntax and type checking belong in CI even for on-prem; the providers are 27 MB to 36 MB each and need a registry or a mirror to install, which matters in an air-gapped data centre (terraform providers mirror is the tool for that); and a plan fails at the provider configuration the moment it cannot reach the API, before any resource is evaluated. In a real environment that line is where DNS, firewall and certificate problems show up, and allow_unverified_ssl = true is only acceptable until the vCenter certificate is trusted.
The same block shape applies to Proxmox (endpoint, api_token) and libvirt (uri = "qemu+ssh://root@kvm-01/system"), and the libvirt provider has the extra advantage that its API is reachable over SSH, so any KVM host becomes Terraform-manageable without installing anything on it.
5. Bare metal - MAAS
For physical servers the pattern needs one more piece: something that can PXE-boot and image a machine. Canonical's MAAS does that and exposes an API, and the canonical/maas provider turns a rack into Terraform resources:
 1provider "maas" {
 2  api_url     = "http://maas.example.internal:5240/MAAS"
 3  api_key     = var.maas_api_key
 4  api_version = "2.0"
 5}
 6
 7resource "maas_instance" "db" {
 8  allocate_params {
 9    min_cpu_count = 8
10    min_memory    = 32768
11    tags          = ["nvme"]
12  }
13  deploy_params {
14    distro_series = "jammy"
15    user_data     = file("cloud-init.yaml")
16  }
17}
allocate_params picks a machine from the pool that matches, deploy_params images it. I have not run MAAS myself; the block above follows the provider's documentation and I include it because it is the only route that gives bare metal the same create/read/destroy loop as a VM. Without MAAS (or an equivalent such as Tinkerbell or a vendor's Redfish API), bare metal falls into the next section.
6. Plain servers over SSH - null resource and remote-exec
When there is no API, Terraform can still reach a server over SSH with provisioners. A null_resource with a trigger on the script's hash, a file provisioner to copy it and remote-exec to run it:
 1resource "null_resource" "server" {
 2  triggers = { script_hash = filemd5("${path.module}/setup.sh") }
 3
 4  connection {
 5    type        = "ssh"
 6    host        = "127.0.0.1"
 7    user        = "runner"
 8    private_key = file("${path.module}/key")
 9  }
10  provisioner "file" {
11    source      = "setup.sh"
12    destination = "/tmp/setup.sh"
13  }
14  provisioner "remote-exec" {
15    inline = ["bash /tmp/setup.sh"]
16  }
17}
 1$ terraform apply -auto-approve
 2null_resource.server: Provisioning with 'file'...
 3null_resource.server: Provisioning with 'remote-exec'...
 4null_resource.server (remote-exec): Connecting to remote host via SSH...
 5null_resource.server (remote-exec):   Host: 127.0.0.1
 6null_resource.server (remote-exec):   User: runner
 7null_resource.server (remote-exec):   Private key: true
 8null_resource.server (remote-exec): Connected!
 9null_resource.server (remote-exec): configuring runnervm8k3b6 as runner
10null_resource.server (remote-exec): done
11null_resource.server: Creation complete after 1s [id=4579479065449266934]
12Apply complete! Resources: 1 added, 0 changed, 0 destroyed.
13
14$ cat /tmp/app/VERSION
15v1
16
17$ terraform apply -auto-approve
18No changes. Your infrastructure matches the configuration.
The second apply did nothing, which sounds right until you realise why: Terraform did not check the server. It compared the trigger (the script's MD5) with the state file. If someone wiped /tmp/app on the server, the next plan would still say "No changes". Change the script and the resource is replaced and the script re-runs:
 1$ sed -i 's/v1/v2/' setup.sh
 2$ terraform apply -auto-approve
 3  # null_resource.server must be replaced
 4-/+ resource "null_resource" "server" {
 5      ~ triggers = { # forces replacement
 6          ~ "script_hash" = "9519710c1836e480dd3bb4d0b7631f0d" -> "ad990c002195c492ad326d4e27406cfd"
 7        }
 8    }
 9null_resource.server (remote-exec): configuring runnervm8k3b6 as runner
10Apply complete! Resources: 1 added, 0 changed, 1 destroyed.
11
12$ cat /tmp/app/VERSION
13v2
That is the honest capability: run a script when its content changes. HashiCorp's own provisioner documentation calls provisioners a last resort for this reason. I go through the connection block and the failure modes in Terraform provisioners and the trigger patterns in null_resource in Terraform.
7. Where Ansible takes over
The division of labour that has worked for me on-premises:
- Terraform owns everything that has an API: the VM (vSphere, Proxmox, libvirt), its disks, its network, its DNS record, the load balancer entry. It knows whether those exist and fixes drift.
- Ansible owns what is inside the VM: packages, config files, services, users. It reads the machine on every run (
changed=0when nothing needs doing), which is exactly whatremote-execcannot do. - The hand-off is an inventory: Terraform writes the IPs it created to a file or to an
output, Ansible reads them.
I built that exact pipeline in the production web app with Terraform and Ansible, and the module boundaries that keep the Terraform half reusable across sites are in Terraform modules.
8. What broke when I ran this
Everything in this post ran as one script on a GitHub Actions runner on 2026-10-16, Terraform 1.14.3, Docker 28.0.4.
1. Terraform told me it was out of date before anything else. I pinned 1.14.3 in the script so the output is reproducible, and the first line it printed was Your version of Terraform is out of date! The latest version is 1.16.6. Harmless here, but on-prem jump hosts often run a years-old Terraform, and a provider that needs a newer protocol fails with a much less helpful message; pin required_version in the configuration so the failure is explicit.
2. The vSphere error came from DNS, and it would have come from a firewall just the same. lookup vcenter.example.internal ... no such host is the first line of the plan, and nothing about the VM resource is evaluated. On a real network the equivalent is a timeout from a firewall rule, so when a plan hangs for a minute on-prem, check port 443 to vCenter before reading the HCL.
3. remote-exec said "No changes" after I could have broken the server. Nothing on the server was checked on the second apply, only the trigger in state. I knew this in theory; seeing No changes. Your infrastructure matches the configuration. printed for a server Terraform never looked at is the clearest argument for a real provider or for Ansible.
4. The containers showed Up Less than a second while already serving 200. Docker reports status from the container's start time; the nginx image answers immediately. For VMs the gap between "created" and "usable" is minutes, and the hypervisor providers expose wait_for_guest_net_timeout (vSphere) and similar settings for that; plan for it rather than chaining a remote-exec that connects too early.
9. Conclusion
To summarise:
- Terraform provisions on-premises infrastructure through providers for vSphere, Proxmox, libvirt, MAAS and Docker, with the same plan, apply, drift and destroy loop as the cloud.
- The requirement is an API. Validate passes without one; plan does not.
- The Docker provider is a free way to learn the on-prem workflow: 4 resources in 4.5 seconds, drift detected and repaired.
- Over bare SSH,
null_resourceplusremote-execruns a script when it changes and nothing more; it never reads the server. - Let Terraform own the API-managed resources and Ansible own the inside of the machine.
Did this save you a debugging session? Stay in the loop -
- Subscribe on YouTube - every post here has a screen-recorded companion video.
- Code on GitHub - the repositories, Terraform and scripts behind these posts.