Terraform null_resource Explained - Triggers, local-exec and remote-exec Examples, and When to Use terraform_data Instead

Terraform null_resource is one of the features which is underused by DevOps professionals. When I first looked at Terraform's documentation for null_resource I felt they had not put much effort into explaining it. But once I tried it myself, I started using it in almost every project - it is the standard way to run a script or a command as part of terraform apply when there is no real resource to attach it to.
In this blog I will explain what null_resource is, how the triggers decide when it runs again, and the real use cases with working code. And because a lot has changed since I recorded the video, I have added what HashiCorp recommends today - the built-in terraform_data resource, which does the same job without a provider, and how to migrate to it.
What is null_resource? - As the name says, the prefix null means this resource does not create anything in your cloud infrastructure (AWS, Google Cloud, Azure). It is a placeholder resource from the hashicorp/null provider whose only job is to be a container for provisioners - and it has an entry in the Terraform state like any other resource, so Terraform knows whether it has already "created" it.
Terraform null_resource is typically used to -
- Run a local shell command or script during apply (
local-exec)- Run commands on a remote machine over SSH after it is created (
remote-exec)- Re-run those commands when something specific changes, using
triggers- Act as a dependency anchor between resources that have no natural relationship
Read more on - How to use Terraform provisioners (local-exec, remote-exec, file) and how to handle null values with a default value
Table of Content
- How does Terraform null_resource work?
- What is the triggers block inside null_resource?
- Use Case 1 - null_resource with the local-exec provisioner
- Use Case 2 - null_resource with the remote-exec provisioner
- Use Case 3 - Run the null_resource on every apply with timestamp()
- Use Case 4 - null_resource as a dependency anchor and for destroy-time actions
- terraform_data - the built-in replacement for null_resource (Terraform 1.4+)
- Advantages and limits of null_resource
- Common errors and mistakes
- Conclusion
1. How does Terraform null_resource work?
A null_resource follows the normal resource lifecycle - create, then no-op on every later apply, then destroy - it just does not call any cloud API. The provisioners attached to it run when the resource is created (and, with when = destroy, when it is destroyed).
So the key thing to understand is - the provisioner runs on the first apply, and then never again, until something forces the null_resource to be replaced. That "something" is the triggers block in the next section.
Example - here is the simplest possible null_resource -
 1# main.tf
 2
 3terraform {
 4  required_providers {
 5    aws = {
 6      source  = "hashicorp/aws"
 7      version = "~> 6.0"
 8    }
 9    null = {
10      source  = "hashicorp/null"
11      version = "~> 3.2"
12    }
13  }
14}
15
16provider "aws" {
17  region = "eu-central-1"
18}
19
20resource "aws_instance" "ec2_example" {
21  ami           = "ami-0a1b2c3d4e5f67890"   # use a current Ubuntu AMI for your region
22  instance_type = "t3.micro"
23  tags = {
24    Name = "Terraform EC2"
25  }
26}
27
28# The following null_resource prints "Hello World" on the machine running terraform
29resource "null_resource" "null_resource_simple" {
30  provisioner "local-exec" {
31    command = "echo Hello World"
32  }
33}
Output -

1null_resource.null_resource_simple: Creating...
2null_resource.null_resource_simple: Provisioning with 'local-exec'...
3null_resource.null_resource_simple (local-exec): Executing: ["/bin/sh" "-c" "echo Hello World"]
4null_resource.null_resource_simple (local-exec): Hello World
5null_resource.null_resource_simple: Creation complete after 0s [id=5218314261232384712]
Run terraform apply a second time and you get No changes. Your infrastructure matches the configuration. - the null_resource exists in the state with that random id, so it is not created again and the command does not run again. (You will also notice terraform init now downloads the null provider - that is the small price of null_resource, and the reason terraform_data exists.)
2. What is the triggers block inside null_resource?
triggers is a map of strings inside the null_resource. Terraform stores it in the state, and the rule is simple - "a map of arbitrary strings that, when changed, will force the null resource to be replaced". Replacing the resource means destroy plus create, and create means the provisioners run again.
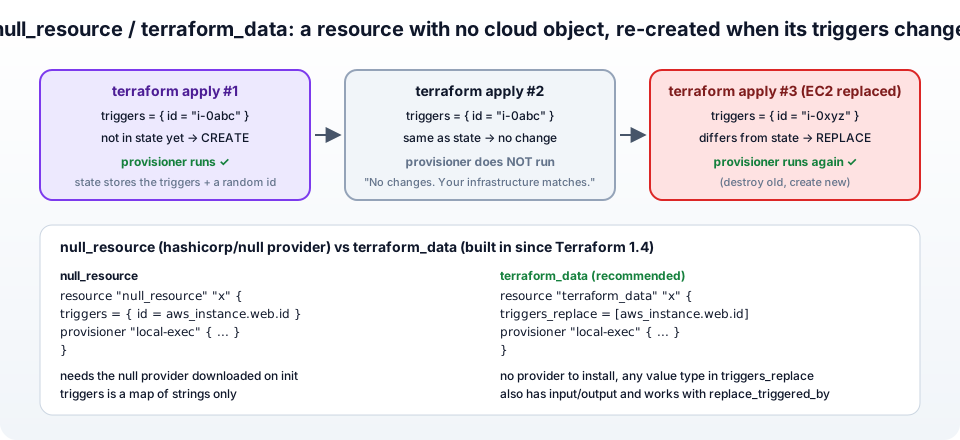
So you choose what should re-run the script by putting it in the triggers -
- The id of an EC2 instance - the script runs once per instance; if the instance is replaced (new AMI, new type that forces replacement), the id changes and the script runs again on the new instance.
- The hash of a file -
filemd5("install.sh")re-runs the script when the script itself changes. - A version variable - bump
var.bootstrap_versionto re-run on demand. timestamp()- a new value every apply, so the script runs every apply (Use Case 3).
Example -
 1resource "aws_instance" "ec2_example" {
 2  ami           = "ami-0a1b2c3d4e5f67890"
 3  instance_type = "t3.micro"
 4  tags = {
 5    Name = "Terraform EC2"
 6  }
 7}
 8
 9# This null_resource re-runs its provisioner only when the EC2 instance id changes
10resource "null_resource" "null_resource_simple" {
11
12  triggers = {
13    instance_id = aws_instance.ec2_example.id
14    script_hash = filemd5("${path.module}/install.sh")
15  }
16
17  provisioner "local-exec" {
18    command = "echo Hello World from instance ${aws_instance.ec2_example.id}"
19  }
20}
Two details worth knowing -
- The map values must be strings. A list or a number has to be converted -
join(",", aws_instance.cluster[*].id)for a list of ids,tostring(var.revision)for a number. - Referencing
aws_instance.ec2_example.idin triggers also creates an implicit dependency, so the null_resource is always created after the instance. You do not needdepends_onfor that.
Use Case 1 - null_resource with the local-exec provisioner
The local-exec provisioner runs a command on the machine where you run terraform - your laptop or the CI runner - not on the cloud resource. With null_resource and local-exec you can do everything your shell can do.
1. Run multiple commands - use a heredoc for several lines -
 1resource "null_resource" "install_istio" {
 2
 3  triggers = {
 4    cluster_id = aws_eks_cluster.main.id
 5  }
 6
 7  provisioner "local-exec" {
 8    command = <<-EOT
 9      chmod +x install-istio.sh
10      ./install-istio.sh
11    EOT
12  }
13}
2. Create a file, call an API, update a kubeconfig - anything with a CLI -
 1resource "null_resource" "kubeconfig" {
 2
 3  triggers = {
 4    cluster_id = aws_eks_cluster.main.id
 5  }
 6
 7  provisioner "local-exec" {
 8    command = "aws eks update-kubeconfig --name ${aws_eks_cluster.main.name} --region eu-central-1"
 9  }
10}
3. Pass variables through the environment and pick the interpreter - this is better than string interpolation when values contain quotes or spaces, and it is how you run PowerShell or Python instead of /bin/sh -
 1resource "null_resource" "notify" {
 2  triggers = {
 3    instance_id = aws_instance.ec2_example.id
 4  }
 5
 6  provisioner "local-exec" {
 7    interpreter = ["/bin/bash", "-c"]
 8    environment = {
 9      INSTANCE_IP = aws_instance.ec2_example.public_ip
10      SLACK_URL   = var.slack_webhook      # sensitive values are fine here, they are not printed
11    }
12    command = "curl -s -X POST -d \"{\\\"text\\\": \\\"New instance $INSTANCE_IP\\\"}\" \"$SLACK_URL\""
13  }
14}
I hope the above examples are enough for you to explore the possibilities of null_resource with local-exec. The full option list (working_dir, interpreter, environment, quiet) is in the local-exec provisioner documentation.
Use Case 2 - null_resource with the remote-exec provisioner
The second use case is remote-exec, which connects to a machine over SSH (or WinRM) and runs commands there. The typical flow -
- Create the EC2 instance
- Create a null_resource with a
connectionblock and a remote-exec provisioner - Terraform SSHes into the instance after it is created
- The inline commands run on the instance
Here is the working code. (The first version of this post had host = ec2_example.id - that was a typo, you need the public IP or DNS name of the instance, and the full resource address.)
 1resource "aws_instance" "ec2_example" {
 2  ami                    = "ami-0a1b2c3d4e5f67890"
 3  instance_type          = "t3.micro"
 4  key_name               = "aws_key"
 5  vpc_security_group_ids = [aws_security_group.allow_ssh.id]
 6  tags = {
 7    Name = "Terraform EC2"
 8  }
 9}
10
11resource "null_resource" "null_resource_with_remote_exec" {
12
13  triggers = {
14    instance_id = aws_instance.ec2_example.id
15  }
16
17  connection {
18    type        = "ssh"
19    host        = aws_instance.ec2_example.public_ip
20    user        = "ubuntu"
21    private_key = file("~/.ssh/aws_key")
22    timeout     = "4m"
23  }
24
25  provisioner "remote-exec" {
26    inline = [
27      "touch hello.txt",
28      "echo helloworld from the remote provisioner >> hello.txt",
29    ]
30  }
31}
Why put the remote-exec in a null_resource instead of directly inside the aws_instance? Because then you can re-run it by changing the triggers (for example after editing the script) without replacing the instance. A provisioner inside the instance block only runs when the instance itself is created. I have covered remote-exec, the file provisioner and the SSH connection details in the Terraform provisioner post, and how to SSH into the EC2 instance created by Terraform.
Note - for bootstrapping a server, HashiCorp's own recommendation is to prefer cloud-init / user_data over
remote-exec, because it does not need SSH access from the Terraform machine. See my post on Terraform user_data. Useremote-execfor the cases user_data cannot cover - running something after another resource exists, or re-running on demand.
Use Case 3 - Run the null_resource on every apply with timestamp()
Sometimes you really want the command to run on every terraform apply - a cache purge, a notification, a smoke test. Put a value in the triggers which is different every time. In the first version of this post I used time() - that function does not exist in Terraform, a few of you pointed it out in the comments. The correct function is timestamp() -
 1# This null_resource is replaced on every apply, because timestamp() is different every time
 2resource "null_resource" "run_every_apply" {
 3
 4  triggers = {
 5    always_run = timestamp()
 6  }
 7
 8  provisioner "local-exec" {
 9    command = "echo Hello World at ${timestamp()}"
10  }
11}
Every terraform plan will now show the null_resource as must be replaced, which also means every plan is dirty - you lose the clean "No changes" signal. Use it sparingly, and never in a module that other teams consume. If you only need to re-run on demand, a version variable is cleaner -
 1variable "bootstrap_version" {
 2  type    = number
 3  default = 1          # bump to 2 to re-run the provisioner
 4}
 5
 6resource "null_resource" "bootstrap" {
 7  triggers = {
 8    version = tostring(var.bootstrap_version)
 9  }
10  provisioner "local-exec" {
11    command = "./bootstrap.sh"
12  }
13}
Use Case 4 - null_resource as a dependency anchor and for destroy-time actions
Dependency anchor - a null_resource can wait for several resources and give the rest of the configuration one thing to depend on. The classic example is "run the cluster bootstrap once all three instances exist" from the official docs -
 1resource "aws_instance" "cluster" {
 2  count         = 3
 3  ami           = "ami-0a1b2c3d4e5f67890"
 4  instance_type = "t3.micro"
 5}
 6
 7resource "null_resource" "cluster" {
 8  # changes to any instance of the cluster require re-provisioning
 9  triggers = {
10    cluster_instance_ids = join(",", aws_instance.cluster[*].id)
11  }
12
13  connection {
14    host        = element(aws_instance.cluster[*].public_ip, 0)
15    user        = "ubuntu"
16    private_key = file("~/.ssh/aws_key")
17  }
18
19  provisioner "remote-exec" {
20    inline = [
21      "bootstrap-cluster.sh ${join(" ", aws_instance.cluster[*].private_ip)}",
22    ]
23  }
24}
Destroy-time actions - with when = destroy the provisioner runs when the null_resource is destroyed, which is how you deregister a node, drain a cluster or clean up something Terraform does not manage -
 1resource "null_resource" "deregister" {
 2  triggers = {
 3    node_name = aws_instance.ec2_example.tags["Name"]
 4  }
 5
 6  provisioner "local-exec" {
 7    when       = destroy
 8    command    = "./deregister-node.sh ${self.triggers.node_name}"
 9    on_failure = continue       # do not block terraform destroy if the script fails
10  }
11}
Note the self.triggers.node_name - a destroy-time provisioner may only reference self, count.index and each.key, which is exactly why the value is stored in the triggers. This is also the reason to stop and think about how you manage the state file - the triggers live there.
terraform_data - the built-in replacement for null_resource (Terraform 1.4+)
Since Terraform 1.4, you no longer need the null provider. The terraform_data resource is built into Terraform itself (provider terraform.io/builtin/terraform), and the null_resource documentation now says it plainly - "On Terraform 1.4 and later, use the terraform_data resource type".
It does everything null_resource does, with a few improvements -
null_resource | terraform_data | |
|---|---|---|
| Provider | hashicorp/null, downloaded on init | built in, nothing to download |
| Re-run condition | triggers - a map of strings | triggers_replace - any value (list, object, id, hash) |
| Store a value in state | no | input argument, read back as output |
Use with lifecycle { replace_triggered_by } | no | yes - a plain variable can trigger replacement of another resource |
The hello-world example becomes -
 1resource "terraform_data" "bootstrap" {
 2  triggers_replace = [
 3    aws_instance.ec2_example.id,
 4    filemd5("${path.module}/install.sh"),
 5  ]
 6
 7  provisioner "local-exec" {
 8    command = "./install.sh ${aws_instance.ec2_example.public_ip}"
 9  }
10}
No string conversion, no join, a list is fine. And the input / replace_triggered_by combination solves an old problem - replacing a resource when a variable changes, which null_resource could never do -
 1variable "revision" {
 2  default = 1
 3}
 4
 5resource "terraform_data" "replacement" {
 6  input = var.revision
 7}
 8
 9resource "aws_instance" "ec2_example" {
10  ami           = "ami-0a1b2c3d4e5f67890"
11  instance_type = "t3.micro"
12
13  lifecycle {
14    replace_triggered_by = [terraform_data.replacement]
15  }
16}
Migrating an existing null_resource - since Terraform 1.9 you can use a moved block, so the state is renamed without a destroy and re-create -
1moved {
2  from = null_resource.bootstrap
3  to   = terraform_data.bootstrap
4}
Rename triggers to triggers_replace (and turn the map into a list of its values), run terraform plan, and you should see Plan: 0 to add, 0 to change, 0 to destroy with a "moved" note. Then you can remove the null provider from required_providers.
My recommendation for new code - use terraform_data. Keep null_resource only where you must support Terraform older than 1.4, or where a module you consume still uses it.
Advantages and limits of null_resource
The advantages -
- No infrastructure created - run a script, call an API, update a kubeconfig as part of the apply, without a fake cloud resource.
- Precise re-run control - the triggers decide exactly when the action repeats - per instance, per script change, per version bump, or every apply.
- Dependency anchor - one thing to
depends_on, after many resources. - Destroy-time hooks -
when = destroyfor clean-up Terraform cannot do natively. - Any provisioner -
local-exec,remote-execandfile.
And the limits you should respect -
- Provisioners are a last resort in HashiCorp's own words. They are not idempotent, Terraform cannot see what the script did, and a failed provisioner taints the resource. If a provider resource or a data source can do the job, use that.
- The output of the script is not in the state - you cannot reference it from other resources. For that, use the external data source or a data source.
local-execruns where Terraform runs. In CI that machine may not have the tools (aws,kubectl,curl) you assume.
Common errors and mistakes
1. The provisioner ran once and never again - Expected. Nothing in triggers changed. Add the value that should re-run it (instance id, file hash, version).
2. The provisioner runs on every apply and every plan is dirty - You have timestamp() (or uuid()) in the triggers. Replace it with a version variable unless "every apply" is really what you want.
3. Error: Call to unknown function; There is no function named "time" - The function is timestamp(). (Yes, the first version of this post had that bug.)
4. Error: Incorrect attribute value type; Inappropriate value for attribute "triggers": element "ids": string required - null_resource triggers must be strings. Use join(",", list) or tostring(number), or switch to terraform_data, which accepts any type.
5. Error: timeout - last error: dial tcp x.x.x.x:22: i/o timeout on remote-exec - Terraform cannot reach port 22 - security group, wrong host (private IP from outside the VPC), or the instance is not ready yet. Check the connection block and the security group; this post walks through it.
6. Error: remote-exec provisioner error ... Permission denied (publickey) - Wrong user for the AMI (ubuntu for Ubuntu, ec2-user for Amazon Linux) or wrong private_key.
7. Error: Provisioner "local-exec" failed ... exit status 127 - The command or tool is not installed on the machine running Terraform. Install it, or set interpreter to an absolute path.
8. Invalid reference from destroy provisioner - A when = destroy provisioner referenced another resource. Only self, count.index and each.key are allowed - put the value in triggers and read it from self.triggers.
9. The null_resource is tainted after a failed run - A failed provisioner marks the resource as tainted and it will be recreated (and the provisioner re-run) on the next apply. That is usually what you want. If not, terraform untaint null_resource.<name>.
Conclusion
null_resource is a container for provisioners with a lifecycle of its own, and triggers is the dial that decides when the provisioners run again. Use it for the glue that infrastructure code always needs - bootstrap scripts, kubeconfig updates, notifications, clean-up on destroy - and keep it out of the places where a provider resource or a data source does the job properly.
And on any Terraform from 1.4 onwards, reach for terraform_data with triggers_replace first. It is the same idea, with no extra provider and fewer type conversions. The official references are the null_resource documentation, the terraform_data documentation and the provisioner overview, and the rest of my Terraform series is below.
Read More - Terragrunt -