kubectl delete pod - delete one pod, all pods in a namespace, by label or status, force delete, and a pod stuck in Terminating (tested on Kubernetes v1.37)
TL;DR
- One pod:
kubectl delete pod NAME -n NAMESPACE. If a Deployment owns it, the ReplicaSet creates a replacement within seconds; in my run the delete took 2.3 seconds and the new pod wasRunning5 seconds later. - All pods in a namespace:
kubectl delete pods --all -n NAMESPACE. Owned pods come back, bare pods are gone for good. - Stop them coming back: delete the owner,
kubectl delete deployment NAME, not the pods. - Only the broken ones:
kubectl delete pods --field-selector=status.phase=Failed -n NAMESPACEremoves crashed and evicted pods and leaves running ones alone. - Force:
--grace-period=0 --forcereturned in 70 ms where a normal delete of a pod ignoring SIGTERM took 60.7 seconds. It does not help with a pod stuck inTerminatingbecause of a finalizer;kubectl patch pod NAME -p '{"metadata":{"finalizers":null}}' --type=mergedoes. - Every output below is from a kind cluster running Kubernetes v1.37.0 with kubectl v1.37.1, captured on 2026-10-15.
- Not your exact case? The closest post on this site is kubectl recreate pods.
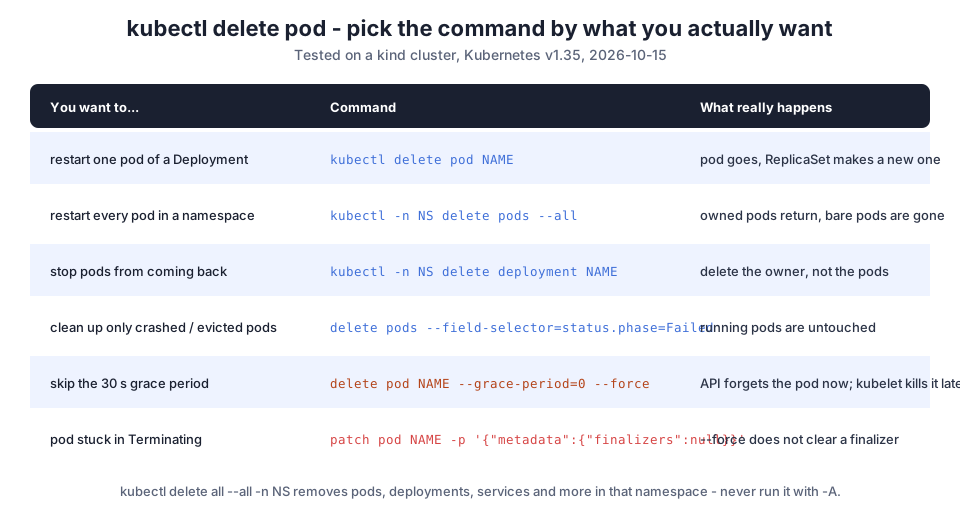
I wrote the first version of this post in 2021 as a list of commands. For this rewrite I ran every one of them on a fresh cluster and timed them, because the questions people actually bring here are not "what is the command" but "why did the pod come back", "why is it stuck in Terminating" and "is --force safe". The answers are in the output.
Table of Content
- The commands at a glance
- The cluster I used
- Delete one pod, and why it comes back
- Delete all pods in a namespace
- Delete by label, and only the failed or evicted pods
- Grace period and force delete, timed
- A pod stuck in Terminating
- Delete the owner, the whole namespace, or everything in it
- Across all namespaces, safely
- What broke when I ran this
- Conclusion
1. The commands at a glance
| You want to | Command | Measured |
|---|---|---|
| restart one pod of a Deployment | kubectl -n NS delete pod NAME | 2,340 ms, replacement running 5 s later |
| restart every pod in a namespace | kubectl -n NS delete pods --all | 1,069 ms for 4 pods |
| remove only crashed or evicted pods | kubectl -n NS delete pods --field-selector=status.phase=Failed | running pods untouched |
| remove pods by label | kubectl -n NS delete pods -l app=web | add --wait=false to return at once |
| stop pods coming back | kubectl -n NS delete deployment NAME | pods gone, none recreated |
| skip the grace period | kubectl -n NS delete pod NAME --grace-period=0 --force | 70 ms |
| clear a pod stuck in Terminating | kubectl -n NS patch pod NAME -p '{"metadata":{"finalizers":null}}' --type=merge | gone within 2 s |
| remove everything in a namespace | kubectl -n NS delete all --all | pods, services, deployments |
| remove the namespace itself | kubectl delete namespace NS | 5,429 ms |
The full option list is in the kubectl delete reference.
2. The cluster I used
A kind cluster, one namespace, a three-replica Deployment and one standalone pod:
 1$ kind create cluster --name demo --wait 120s
 2 ✓ Ensuring node image (kindest/node:v1.37.0) 🖼️
 3 ✓ Ready after 17s 💚
 4
 5$ kubectl -n demo create deployment web --image=nginx:1.27-alpine --replicas=3
 6deployment.apps/web created
 7$ kubectl -n demo run standalone --image=nginx:1.27-alpine --labels=app=standalone
 8pod/standalone created
 9
10$ kubectl -n demo get pods -o wide
11NAME                  READY   STATUS              RESTARTS   AGE   IP           NODE
12standalone            0/1     ContainerCreating   0          4s    <none>       demo-control-plane
13web-7c6cdd646-9qm2b   1/1     Running             0          4s    10.244.0.6   demo-control-plane
14web-7c6cdd646-9sl29   1/1     Running             0          4s    10.244.0.7   demo-control-plane
15web-7c6cdd646-zqxrv   1/1     Running             0          4s    10.244.0.5   demo-control-plane
The difference between web-* and standalone is the whole story of this post: the first three have an owner, the last one does not. If kind is new to you, my Kubernetes index links the setup posts.
3. Delete one pod, and why it comes back
1$ kubectl -n demo delete pod web-7c6cdd646-9qm2b
2pod "web-7c6cdd646-9qm2b" deleted from demo namespace
3[took 2340 ms]
4
5$ kubectl -n demo get pods -l app=web
6NAME                  READY   STATUS    RESTARTS   AGE
7web-7c6cdd646-9sl29   1/1     Running   0          9s
8web-7c6cdd646-kmq6s   1/1     Running   0          5s
9web-7c6cdd646-zqxrv   1/1     Running   0          9s
The pod I deleted is gone and web-7c6cdd646-kmq6s took its place 5 seconds later. The ReplicaSet behind the Deployment keeps the count at 3 no matter what you delete. That makes delete pod a quick restart, which is usually what you want; if you wanted the pod gone, see section 8. I covered the mechanism in why Kubernetes recreates a deleted pod.
4. Delete all pods in a namespace
 1$ kubectl -n demo delete pods --all
 2pod "standalone" deleted from demo namespace
 3pod "web-7c6cdd646-9sl29" deleted from demo namespace
 4pod "web-7c6cdd646-kmq6s" deleted from demo namespace
 5pod "web-7c6cdd646-zqxrv" deleted from demo namespace
 6[took 1069 ms]
 7
 8$ kubectl -n demo get pods
 9NAME                  READY   STATUS    RESTARTS   AGE
10web-7c6cdd646-66hzr   1/1     Running   0          6s
11web-7c6cdd646-dxj25   1/1     Running   0          6s
12web-7c6cdd646-pgnwm   1/1     Running   0          6s
Four pods deleted in about a second; three came back, standalone did not. --all is scoped to the namespace you name (or your current one), so this is safe to run as long as you are sure of the -n.
5. Delete by label, and only the failed or evicted pods
A label selector targets one application:
1$ kubectl -n demo delete pods -l app=web --wait=false
2pod "web-7c6cdd646-66hzr" deleted from demo namespace
3pod "web-7c6cdd646-dxj25" deleted from demo namespace
4pod "web-7c6cdd646-pgnwm" deleted from demo namespace
--wait=false returns as soon as the API accepts the deletion instead of waiting for the containers to stop. For cleaning up after an incident, a field selector on the pod phase removes only pods that have already failed - crashed one-shot pods and evicted pods both have phase Failed:
1$ kubectl -n demo run crash --image=alpine:3.20 --restart=Never -- sh -c 'exit 1'
2pod/crash created
3
4$ kubectl -n demo get pods --field-selector=status.phase=Failed
5NAME    READY   STATUS   RESTARTS   AGE
6crash   0/1     Error    0          8s
7
8$ kubectl -n demo delete pods --field-selector=status.phase=Failed
9pod "crash" deleted from demo namespace
The running web pods were not touched. Field selectors support status.phase, metadata.name, spec.nodeName and a few others, which also makes "delete every pod on node X" a one-liner.
6. Grace period and force delete, timed
When you delete a pod, Kubernetes sends SIGTERM and waits terminationGracePeriodSeconds (30 by default) before SIGKILL. To see what that costs, I made a pod that ignores SIGTERM with a 60 second grace period:
1$ kubectl -n demo delete pod slow --timeout=90s
2pod "slow" deleted from demo namespace
3[took 60743 ms]
Sixty seconds, exactly the grace period, because the process never exited on its own. The same pod with a forced delete:
1$ kubectl -n demo delete pod slow2 --grace-period=0 --force
2Warning: Immediate deletion does not wait for confirmation that the running resource has been terminated. The resource may continue to run on the cluster indefinitely.
3pod "slow2" force deleted from demo namespace
4[took 70 ms]
Read the warning carefully: --force removes the pod from the API server immediately; the kubelet still has to kill the container afterwards, and if the node is unreachable the process may keep running. For a StatefulSet pod that can mean two copies writing to the same volume. The pod termination section of the docs explains the sequence. My rule: use --force for pods whose node is gone, never as a shortcut for a slow shutdown.
7. A pod stuck in Terminating
A pod with a finalizer cannot be removed until something clears the finalizer. I created one on purpose:
 1apiVersion: v1
 2kind: Pod
 3metadata:
 4  name: stuck
 5  namespace: demo
 6  finalizers: ["example.com/never-done"]
 7spec:
 8  containers:
 9  - name: c
10    image: nginx:1.27-alpine
1$ kubectl -n demo delete pod stuck --timeout=10s
2pod "stuck" deleted from demo namespace
3error: timed out waiting for the condition on pods/stuck
4
5$ kubectl -n demo get pod stuck -o jsonpath='{.metadata.deletionTimestamp} {.metadata.finalizers}'
62026-10-15T22:20:54Z ["example.com/never-done"]
The pod has a deletionTimestamp, so it shows as Terminating, but the finalizer holds it. --force does nothing here:
1$ kubectl -n demo delete pod stuck --grace-period=0 --force --timeout=10s
2pod "stuck" force deleted from demo namespace
3error: timed out waiting for the condition on pods/stuck
4
5$ kubectl -n demo get pod stuck
6NAME    READY   STATUS      RESTARTS   AGE
7stuck   0/1     Completed   0          25s
Clearing the finalizer removes it within a couple of seconds:
1$ kubectl -n demo patch pod stuck -p '{"metadata":{"finalizers":null}}' --type=merge
2pod/stuck patched
3
4$ kubectl -n demo get pod stuck
5Error from server (NotFound): pods "stuck" not found
Before you do this on a real cluster, find out which controller set the finalizer and why it is not finishing; finalizers usually protect something, such as a volume that is still attached. Removing one by hand skips that protection.
8. Delete the owner, the whole namespace, or everything in it
To make Deployment pods stay gone, delete the Deployment:
1$ kubectl -n demo delete deployment web
2deployment.apps "web" deleted from demo namespace
3
4$ kubectl -n demo get pods
5No resources found in demo namespace.
delete all --all removes pods, services, deployments, replicasets and a few other core kinds in one namespace (not ConfigMaps, Secrets, PVCs or CRDs - "all" is a fixed shortlist):
 1$ kubectl -n demo delete all --all
 2pod "api-776fc4695b-6v6b4" deleted from demo namespace
 3pod "api-776fc4695b-qvhs5" deleted from demo namespace
 4service "api" deleted from demo namespace
 5deployment.apps "api" deleted from demo namespace
 6
 7$ kubectl -n demo get all
 8NAME                       READY   STATUS        RESTARTS   AGE
 9pod/api-776fc4695b-h7f78   0/1     Terminating   0          1s
10pod/api-776fc4695b-hl4sl   0/1     Terminating   0          1s
Note the two pods with AGE 1s in Terminating: the ReplicaSet created replacements in the moment between the pods being deleted and the Deployment being deleted, and those are now being terminated too. Deleting the namespace removes everything in it, including the kinds all skips:
1$ kubectl delete namespace demo
2namespace "demo" deleted
3[took 5429 ms]
9. Across all namespaces, safely
kubectl delete pods --all -A deletes the pods in kube-system too (CoreDNS, kube-proxy, the CNI), and I do not recommend typing it. If you need a cluster-wide sweep, list first and exclude the system namespaces:
1kubectl get pods -A -o json \
2  | jq -r '.items[] | select(.metadata.namespace!="kube-system" and .metadata.namespace!="local-path-storage") | "\(.metadata.namespace) \(.metadata.name)"'
On my cluster after the demo namespace was gone, that list was empty and the only pods left were the 3 system ones. Feed the output to kubectl delete pod -n NS NAME only after you have read it. Before deleting anything you might want back, export the YAML of the deployed resources first.
10. What broke when I ran this
I ran everything as a script on a GitHub Actions runner with kind v0.33.0 on 2026-10-15.
1. kubectl version --short no longer exists. The flag was removed, and the command exits 1. kubectl version without flags prints client and server versions (v1.37.1 and v1.37.0 here).
2. The "stuck" pod showed Completed, not Terminating. In kubectl get pods the pod with the finalizer was listed as Completed because its container had already exited by the time I looked; the column shows the container state, and only the deletionTimestamp in the JSON revealed that it was waiting for the finalizer. Do not rely on the STATUS column to spot a stuck pod; check deletionTimestamp.
3. A 60 second grace period really waits 60 seconds. I had set terminationGracePeriodSeconds: 60 to make the point and then watched the delete block for 60.7 seconds. In a rolling update with 20 such pods, that is 20 minutes if your process ignores SIGTERM; make the application handle the signal instead of lowering the grace period.
11. Conclusion
To summarise what I measured:
kubectl delete pod NAMEis a restart when a Deployment owns the pod; delete the Deployment to make it permanent.delete pods --all -n NSclears a namespace's pods in about a second;--field-selector=status.phase=Failedclears only the broken ones.- A normal delete waits for the grace period (60.7 seconds in my test);
--grace-period=0 --forcereturns in milliseconds but leaves the container to be killed later. - A pod stuck in
Terminatinghas a finalizer;--forcedoes not clear it,kubectl patchdoes. - Never run
delete pods --all -A; list and excludekube-systeminstead.
If the pods you deleted are not coming back the way you expected, how Kubernetes recreates pods explains owners and ReplicaSets, and if kubectl itself cannot reach the cluster, start with the connection to the server localhost:8080 was refused.
Did this save you a debugging session? Stay in the loop -
- Subscribe on YouTube - every post here has a screen-recorded companion video.
- Code on GitHub - the repositories, Terraform and scripts behind these posts.